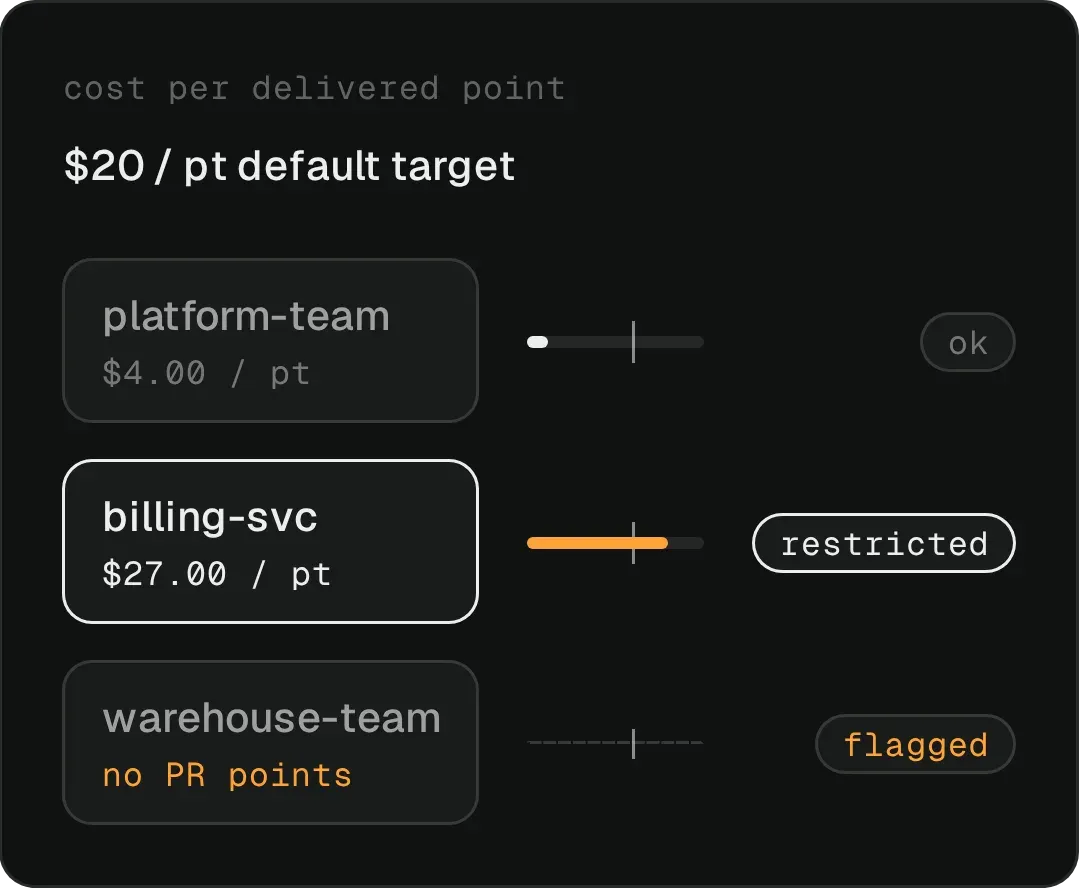
Billing service spends $27.00 per point, above the $20 target, so Pensero routes its premium requests to a lower-cost model.
Billing service$27.00 / pt
Platform team$4.00 / pt
Warehouse teamNo points
Pensero MCPget_ai_spend_breakdown
Which owners spend above the $20 per point target?
Claude
illustrative data
Measure cost per point.
Compare each owner’s agent spend with the delivery points their sessions produced, in USD per point.
Keep premium where it delivers.
Owners within target pass unchanged to the model they asked for. Low delivery is flagged, never blocked.
Route the rest.
When an owner’s $/pt sits above target, premium requests go to a lower-cost model at your provider, with reasoning effort capped.
What your agent spend delivers
See where agent spend goes
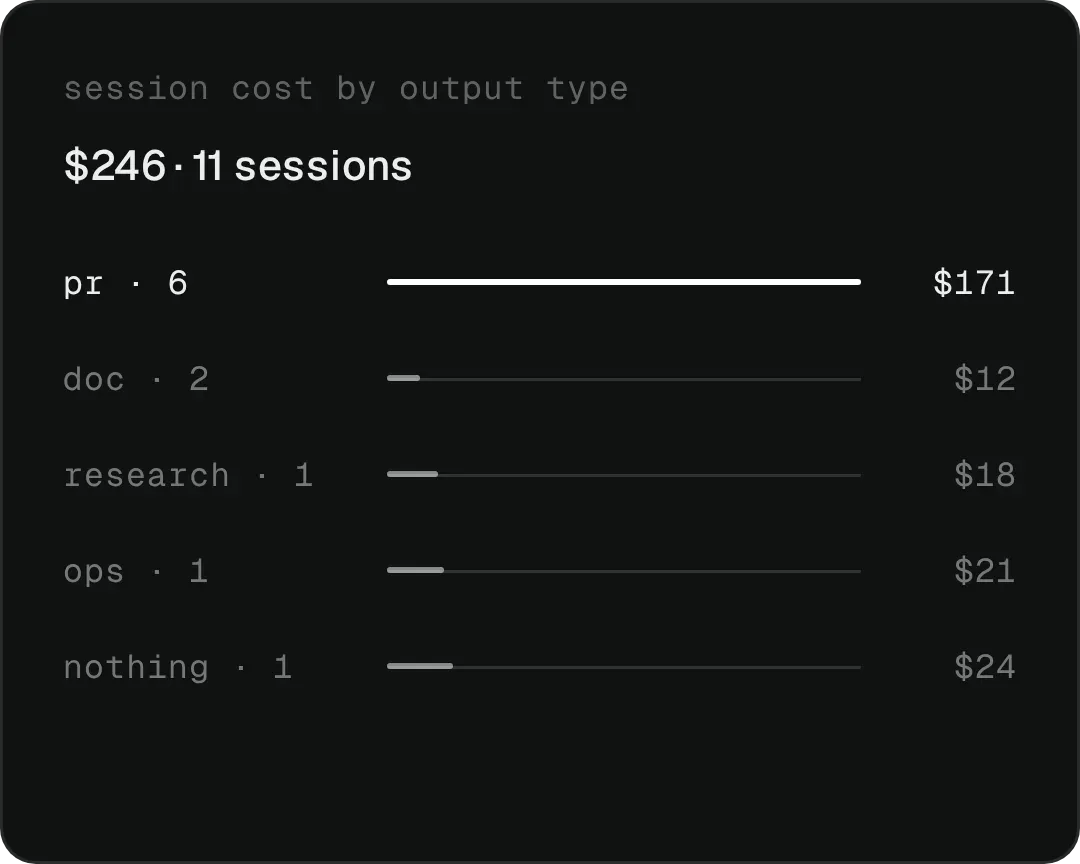
Compare session cost by output type before you change how a team works.
session cost by output typelast 14 days
$246 · 11 sessions
pr · 6$171
doc · 2$12
research · 1$18
ops · 1$21
nothing · 1$24
$22 average per session · PR sessions 70% of spend
Keep the model where it earns its cost
Compare cost per point per owner to decide where an expensive model is worth keeping.
cost per delivered pointtarget $20 / pt
$20 / pt default target
platform-team$4.00 / ptok
billing-svc$27.00 / ptrestricted
warehouse-teamno PR pointsflagged
1 of 3 owners within the $20 / pt target
See the work behind the points
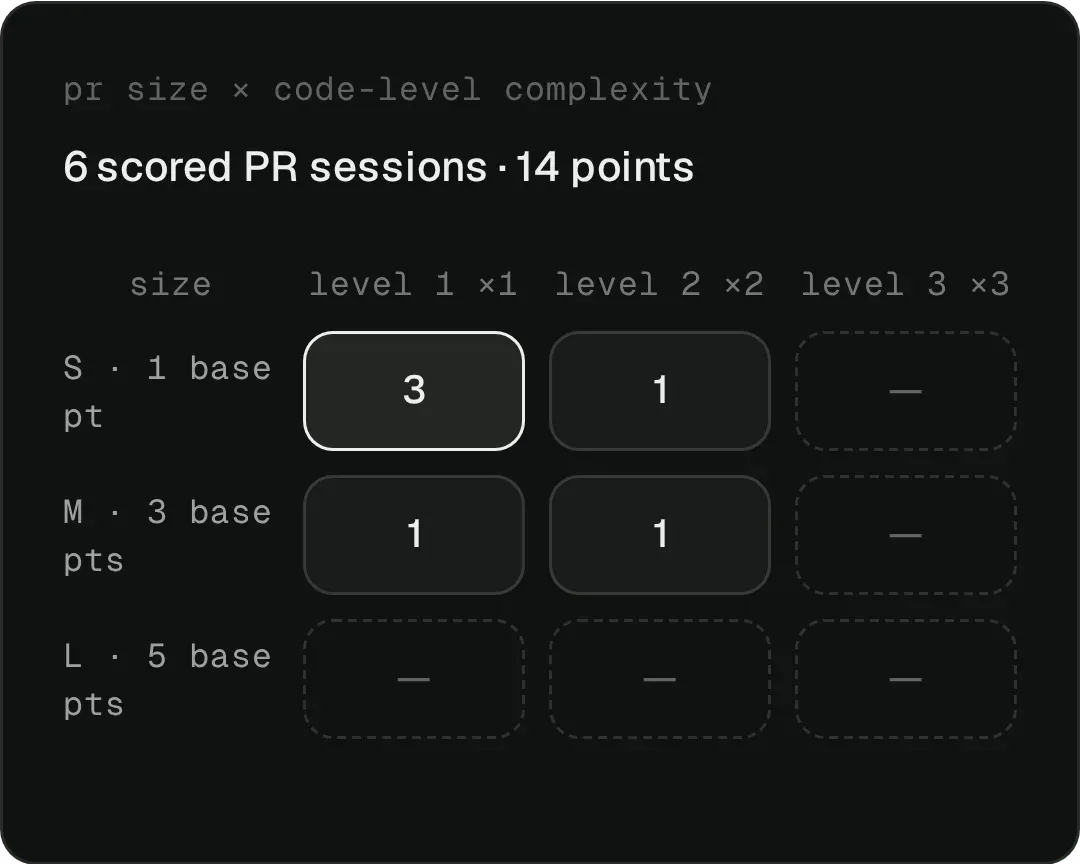
Delivery points multiply the magnitude of each PR by its complexity. Our proprietary technology combines AI, heuristics and ML to give deterministic results.
pr size × code-level complexityscored pr sessions
6 scored PR sessions · 14 points
sizelevel 1 ×1level 2 ×2level 3 ×3S · 1 base pt31—M · 3 base pts11—L · 5 base pts———
2.3 points per scored PR session on average
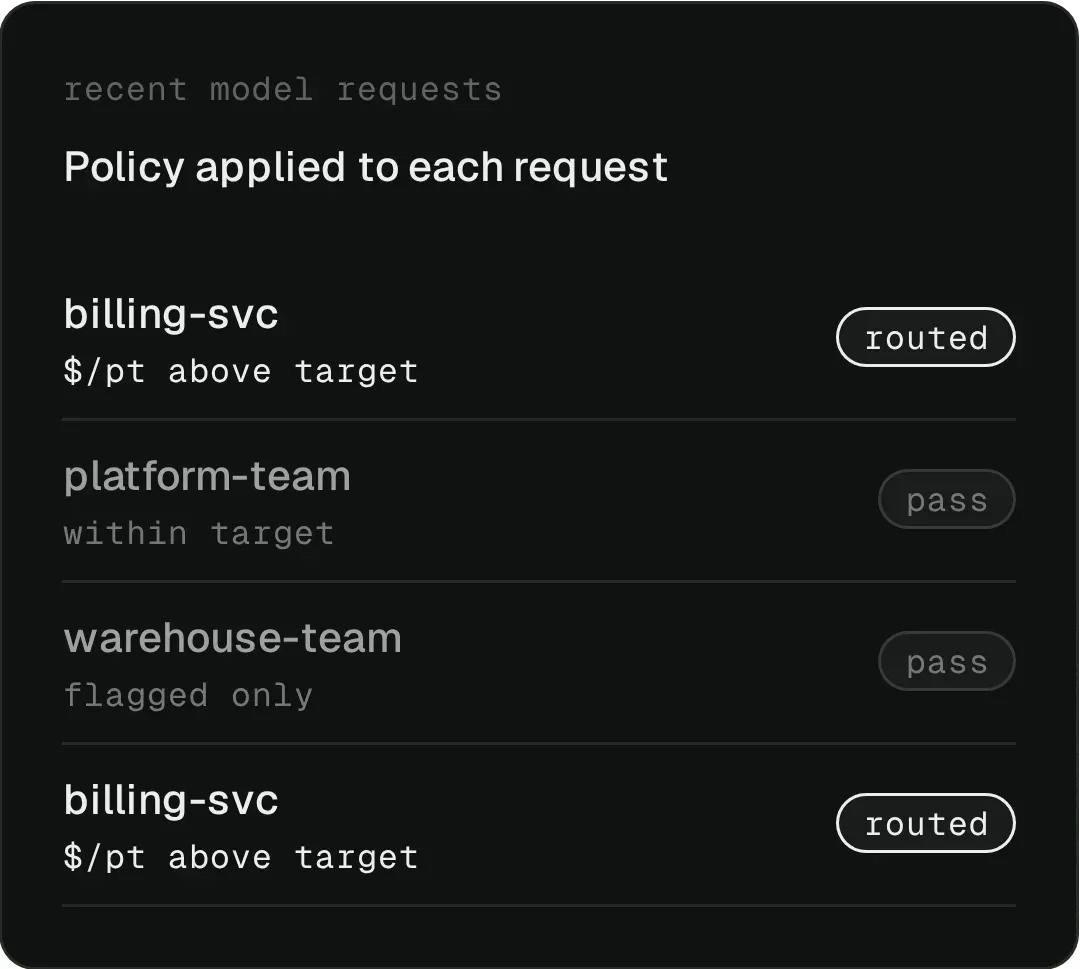
See which requests changed model
Route premium requests to a lower-cost model; investigate low delivery without blocking models.
Compare the cost of token usage with the tasks that sessions delivered. Use USD per delivery point ($/pt) for each owner over a configurable 14-day window.
target $20 / pt · 14-day window
01 · Incoming request
Owner + model
Every request carries the owner it belongs to and the model it asked for.
02 · Owner rating
Check the rating system
Fewer than 3 scored sessions, or no rating? The request passes unchanged.
03 · Owner state
Check cost vs delivery
$/pt against your target. Low delivery passes, flagged only.
04 · Requested model
Premium + restricted?
Yes: fall back to a lower-cost model. Otherwise, pass.
Runs in your VPC
Your session data stays on your host. Send agent requests to any OpenAI-compatible endpoint or LiteLLM provider, including OpenAI, Gemini, vLLM and Ollama, or Bedrock or Anthropic.
one docker compose deployment
Records stay with you.
Proxy, scorer, session database and dashboard run on your host. Session data never leaves it.
Any provider you already use.
Only agent requests and their context go out, to any OpenAI-compatible endpoint or LiteLLM provider.
Score PRs in the cloud or locally.
One Docker Compose deployment, a proxy key and a password-protected dashboard. Add a local PR scoring model if you want.
Agent spend grows fast, and a token bill does not show what the work delivered. Pensero puts the cost of each session next to the work it produced, so you can see which usage pays off.
Which coding agents and models does it support?
Pensero scores Claude Code and Codex CLI sessions today. Agents can use any model provider, such as OpenAI, Anthropic, Gemini, Bedrock or a local model.
Do delivery points measure business impact?
They are a proxy for it. Pensero measures the magnitude and difficulty of the work that each session delivers. Use them together with a review of the work, not to rank people.
How does impact-based routing work?
Pensero compares each owner's spend with the work they delivered. Where a premium model delivers, it stays. Where the cost per point is too high, requests go to a lower-cost model. Low delivery gets a flag, not a block. You set the thresholds.
Does our data stay in our environment?
Pensero runs on your host or VPC. Session data, scores and the dashboard stay there. Model requests go only to the providers that you choose, and these can be local.
How do we deploy it?
Book a call. We deploy it on-prem, on your host or VPC.